TABLE OF CONTENTS
- •What Is a VLF (Virtual Log File)?
- •Need expert support for SQL Server?
- •How Are VLFs Created?
- •What Problems Do Too Many VLFs Cause?
- •Signs in the error log
- •How to Measure Your VLF Count
- •How to Fix a High VLF Count
- •1. Make sure the log is truncated
- •2. Shrink the log
- •3. Grow the log to its target size in controlled steps
- •4. Fix the autogrowth setting for good
- •Watch Out in Always On and Log Shipping Environments
- •Frequently Asked Questions
- •Don’t Let Hidden Problems Stretch Your Restore and Failover Times
Some SQL Server performance problems never show up clearly in a query plan or in wait statistics. A database takes minutes to come online, a restore takes far longer than expected, an Always On secondary keeps falling behind, and the cause is hard to find. Behind many of these problems is an invisible structure inside the transaction log: the VLF (virtual log file) count.
This article explains what VLFs are, how they’re created, which problems too many VLFs cause, how to measure your VLF count, and how to rebuild a log file with a healthy VLF layout, step by step.
What Is a VLF (Virtual Log File)?
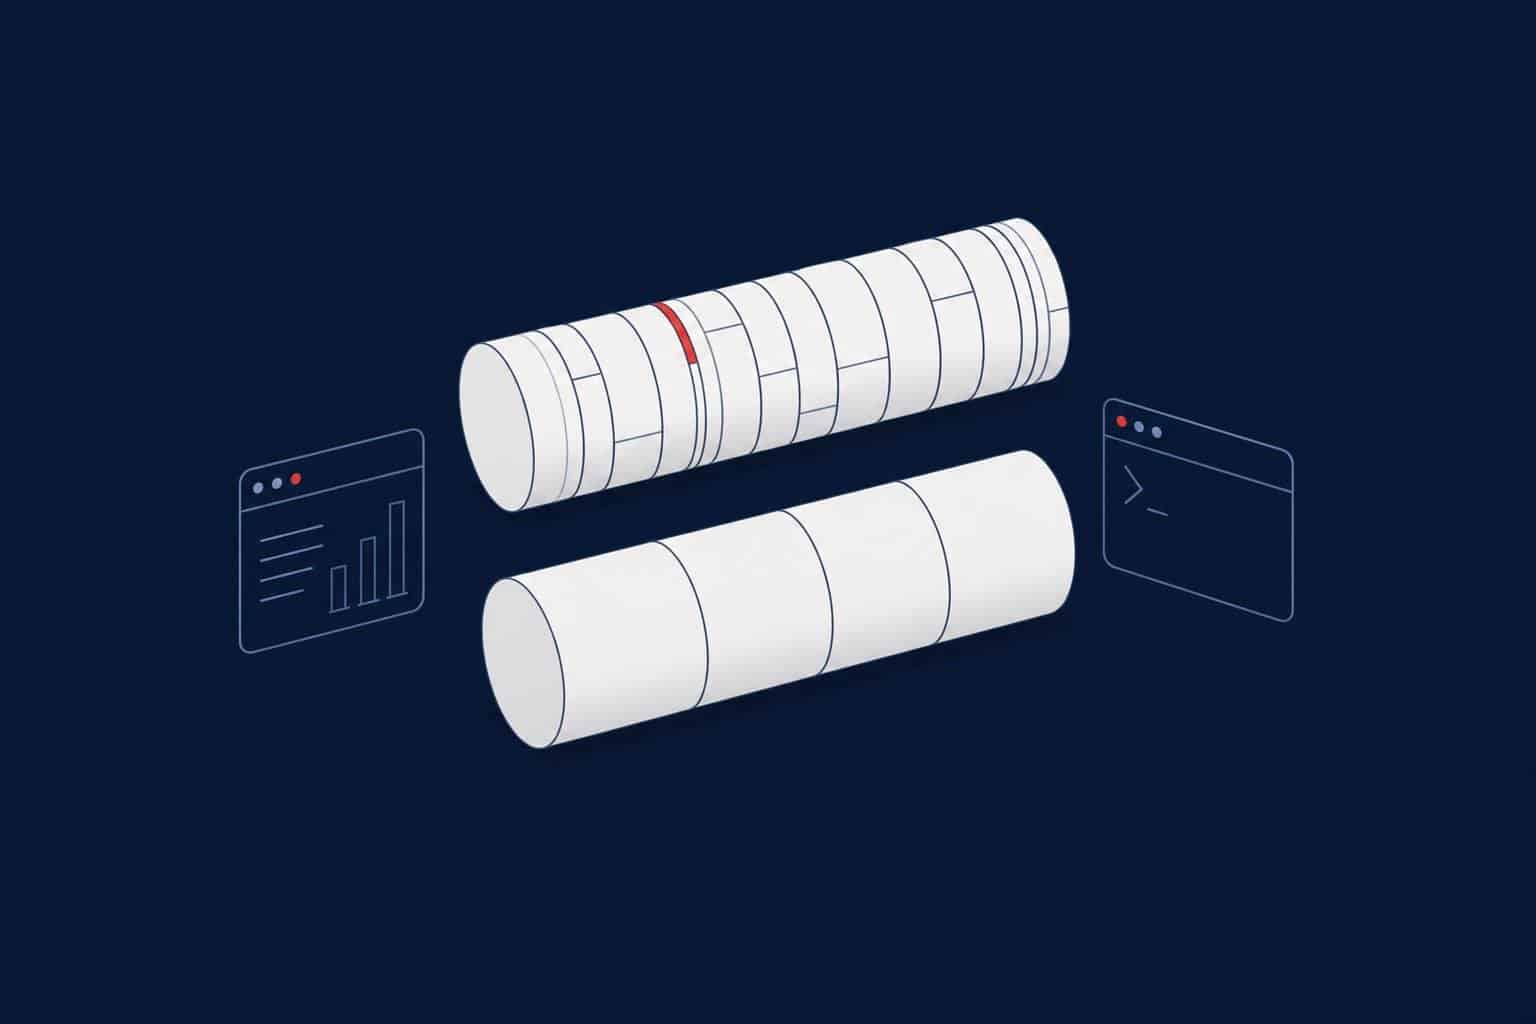
SQL Server internally divides every transaction log file (.ldf) into pieces called virtual log files. The log works through these pieces in a circular way: new records are written to the end of the log, and VLFs that are no longer needed are truncated and reused. Log truncation and log shrink both happen at VLF boundaries.
Administrators can’t set the number or size of VLFs directly. SQL Server decides them itself when the log file is created and every time it grows, based on the size of the growth. In other words, your VLF count is a direct result of how your log file grew.
Need expert support for SQL Server?
Our senior database team supports SQL Server performance tuning, health checks, migrations, Remote DBA services and urgent operational issues.
How Are VLFs Created?
According to the rule Microsoft documents, the number of VLFs created each time the log grows depends on the size of the growth:
| Growth size | VLFs created |
|---|---|
| Less than 1/8 of the current log size (SQL Server 2014 and later) | 1 |
| Less than 64 MB | 4 (SQL Server 2022 and later, up to 64 MB: 1) |
| 64 MB – 1 GB | 8 |
| Larger than 1 GB | 16 |
This is where the problem starts. In a database that has run for years with the old defaults (10% or 1 MB autogrowth for the log), the log may have grown in thousands of small steps. Each small growth adds a few small VLFs, until the log file is made of tens or even hundreds of thousands of them. Since SQL Server 2016, the default log autogrowth for new databases is 64 MB, but databases upgraded or migrated from older versions keep their old settings.
The opposite is a problem too: growing a log in one very large step creates a few very large VLFs. Log truncation then happens in huge chunks and log space isn’t used efficiently. The goal is neither thousands of tiny VLFs nor a handful of giant ones.
What Problems Do Too Many VLFs Cause?
In the first phase of database recovery, SQL Server scans every VLF in the log and builds a list of them. The more VLFs, the longer this takes. According to Microsoft, a large number of VLFs can cause:
- Slow database startup: after a SQL Server restart or a failover, the database takes a very long time to finish recovery.
- Slow restore and attach: restoring or attaching the database takes far longer than expected, which directly extends your RTO in a disaster.
- Slow log backups.
- Replication, CDC and Always On latency: the Log Reader Agent has to scan every VLF for transactional replication, and redo latency grows on Always On secondaries.
- Timeouts when setting up mirroring (errors 1413, 1443 and 1479), and memory errors such as 701 during restore.
These effects become pronounced as the VLF count reaches the tens and hundreds of thousands. Microsoft recommends keeping the total VLF count to a few thousand at most.
Signs in the error log
From SQL Server 2012 onward, when a database with more than 10,000 VLFs starts up, is restored or is attached, SQL Server writes informational message 9017 to the error log: “Database … has more than … virtual log files which is excessive.” If the error log also shows minutes passing between a database’s “Starting up database” message and its recovery “Analysis … Phase 1 of 3” message, that’s another typical sign of a high VLF count. We explain how to read the error log in our SQL Server Error Log guide.
How to Measure Your VLF Count
On SQL Server 2016 SP2 and later, VLF information comes from two dynamic management functions. sys.dm_db_log_info replaces the old DBCC LOGINFO command, and sys.dm_db_log_stats returns summary information. For every database on the server:
SELECT d.name,
       d.recovery_model_desc,
       ls.total_vlf_count,
       ls.active_vlf_count,
       CAST(ls.total_log_size_mb AS decimal(18, 2)) AS total_log_size_mb,
       CAST(ls.total_log_size_mb / NULLIF(ls.total_vlf_count, 0) AS decimal(18, 2)) AS avg_vlf_size_mb,
       ls.log_truncation_holdup_reason
FROM sys.databases AS d
CROSS APPLY sys.dm_db_log_stats(d.database_id) AS ls
WHERE d.state_desc = N'ONLINE'
ORDER BY ls.total_vlf_count DESC;
When you read the results, look at the average VLF size, not just the count. 20,000 VLFs in a 50 GB log (2.5 MB on average) is clearly a problem; 200 VLFs in a 50 GB log (250 MB on average) is a reasonable layout. The log_truncation_holdup_reason column shows why the log can’t be truncated; before fixing VLFs, it should be NOTHING or a transient value.
How to Fix a High VLF Count
The idea is simple: shrink the log file as far as possible, grow it back to the size you need in a few controlled steps, and fix the autogrowth setting. Before you start, make sure you have a restorable backup.
1. Make sure the log is truncated
The log can only shrink if the VLFs at its end aren’t in use. Under the full recovery model, take a log backup first. If log_truncation_holdup_reason shows LOG_BACKUP or ACTIVE_TRANSACTION, deal with that cause first. For details, see SQL Server Transaction Log Too Big?
USE [SalesDB];

BACKUP LOG [SalesDB]
TO DISK = N'E:\Backup\SalesDB_LOG_before_vlf_fix.trn'
WITH COMPRESSION, CHECKSUM;

-- Where are the active VLFs? If the last VLFs are active, the shrink won't reach its target.
SELECT TOP (5) vlf_sequence_number, vlf_begin_offset, vlf_size_mb, vlf_active
FROM sys.dm_db_log_info(DB_ID())
ORDER BY vlf_begin_offset DESC;
2. Shrink the log
-- Logical name of the log file
SELECT name, size / 128 AS size_mb FROM sys.database_files WHERE type = 1;

-- Shrink as far as possible (target in MB)
DBCC SHRINKFILE (N'SalesDB_log', 0);

-- Result: how many VLFs are left?
SELECT COUNT(*) AS vlf_count FROM sys.dm_db_log_info(DB_ID());
If the active log sits in the VLFs at the end of the file, the first attempt may not shrink it far enough. Taking another log backup (in full recovery) and repeating the shrink usually solves this. For more on shrinking, see SQL Server Shrink Best Practices.
3. Grow the log to its target size in controlled steps
Size the log for its real requirement (its usage during the busiest period). Jumping straight to a large target creates very large VLFs; getting there in tiny steps creates too many. A practical approach is to move towards the target in 8 GB steps; since every growth over 1 GB creates 16 VLFs, each step adds VLFs of roughly 512 MB:
-- Target: a 32 GB log with VLFs of roughly 512 MB
ALTER DATABASE [SalesDB] MODIFY FILE (NAME = N'SalesDB_log', SIZE = 8192MB);
ALTER DATABASE [SalesDB] MODIFY FILE (NAME = N'SalesDB_log', SIZE = 16384MB);
ALTER DATABASE [SalesDB] MODIFY FILE (NAME = N'SalesDB_log', SIZE = 24576MB);
ALTER DATABASE [SalesDB] MODIFY FILE (NAME = N'SalesDB_log', SIZE = 32768MB);

-- Fixed autogrowth for future growth
ALTER DATABASE [SalesDB] MODIFY FILE (NAME = N'SalesDB_log', FILEGROWTH = 512MB);
For smaller logs, scale the step size down; for a 4 GB log, for example, 1 GB steps are enough. Microsoft also publishes a script that calculates the optimal VLF layout and growth steps for your current log sizes in the Tiger Toolbox repository on GitHub.
4. Fix the autogrowth setting for good
Warning
Skip this step and the problem comes back within months. Set log autogrowth as a fixed size in MB, not a percentage, and following Microsoft’s recommendation, don’t set it above 1,024 MB. From SQL Server 2022, log growths up to 64 MB benefit from instant file initialization and create a single VLF. Check the autogrowth settings of every log file on the server with:
SELECT DB_NAME(database_id) AS database_name,
       name AS logical_name,
       CAST(size AS bigint) * 8 / 1024 AS size_mb,
       CASE WHEN is_percent_growth = 1
            THEN CAST(growth AS varchar(10)) + ' %'
            ELSE CAST(CAST(growth AS bigint) * 8 / 1024 AS varchar(10)) + ' MB'
       END AS autogrowth
FROM sys.master_files
WHERE type = 1
ORDER BY is_percent_growth DESC, growth;
Every log file growing by a percentage or in very small steps such as 1–10 MB is a candidate for a high VLF count in the future. In the example above, a 512 MB growth on the 32 GB log is less than 1/8 of the current size, so it creates a single 512 MB VLF; the VLF layout stays healthy even as the log grows.
Watch Out in Always On and Log Shipping Environments
Note
In an availability group, log file operations affect every replica. Growing the log on the primary (ALTER DATABASE ... MODIFY FILE) is applied to the secondaries too, so make sure their log disks have enough space as well. A shrink only works if the log records the secondaries haven’t yet received or applied aren’t at the end of the log, so do this work at a quiet time when all replicas are synchronized. For more on Always On architecture, see our SQL Server Always On guide.
Frequently Asked Questions
sys.dm_db_log_info and sys.dm_db_log_stats. They can be used for every database in a single query and return clearer columns.DBCC SHRINKFILE and ALTER DATABASE ... MODIFY FILE all work while the database is online. Still, pick a low-activity window, as growing the log can cause brief slowdowns.Related Reading
- SQL Server Transaction Log Too Big? Causes, Diagnosis and Safe Fixes
- SQL Server Shrink Best Practices: When to Shrink and When Not To
- How to Restore a SQL Server Database: SSMS, T-SQL and Point-in-Time Guide
- SQL Server Error Log: Where to Find It, How to Read It and What to Watch For
- What Is SQL Server Always On? Availability Groups and FCI Guide
- DBA Managed Services
SQL Server Performance Consulting
Don’t Let Hidden Problems Stretch Your Restore and Failover Times
Aryasoft’s senior DBA team reviews and fixes the health of your SQL Server environment end to end, including VLF layout, log sizing, autogrowth settings and restore times.